RankyFy AI SEO brings AI search optimization to WordPress. See exactly which AI crawlers — GPTBot, ClaudeBot, OAI-SearchBot, PerplexityBot, Google-Extended and 30+ more — read your site, track the visitors that ChatGPT, Perplexity, Gemini, Claude and Copilot send you, publish a clean llms.txt, control AI bot access through robots.txt, and fix the issues that keep your content out of AI answers.
AI SEO is to assistants what classic SEO is to search engines: being readable, verifiable and worth quoting when ChatGPT or Perplexity answers a question in your niche. This plugin gives you the measurement and the controls for it.
Install, activate, done — monitoring starts immediately and runs entirely on your own site. No account is needed, and nothing is sent anywhere unless you explicitly enable it.
AI crawler analytics, verified
Anyone can claim to be GPTBot. Every request that claims a known AI crawler is verified against the operator’s published IP ranges, by forward-confirmed reverse DNS, or by cryptographic signature (Web Bot Auth) — and impersonations are counted separately, never as crawls.
- Every AI crawler request logged: bot, page, response, timing.
- Per-crawler detail: purpose (model training, AI search, or fetching a page for a real user), daily trends, crawl sessions, the pages it reads.
- The dashboard answers the first question — are AI crawlers reading my site at all, and which pages have they never seen?
Track AI traffic: visits from ChatGPT, Perplexity and more
AI referral tracking shows every AI referral — the visits that arrive from ChatGPT, Perplexity, Gemini, Claude, Copilot and other assistants — by engine and by landing page, right beside the crawl data for the same page. Crawled vs. AI visits highlights pages AI reads but never sends anyone to: usually a content problem, not a crawling one.
llms.txt generator — plus llms-full.txt and ai.txt
llms.txt is a proposed standard file that gives AI systems a curated map of your most important content. RankyFy AI SEO generates it from what AI crawlers actually read on your site, keeps it updated as content changes, and leaves out pages that are noindex, erroring or blocked. llms-full.txt (full text) and ai.txt (training policy) are included. Your manual edits survive rebuilds, and nothing is served until you switch it on.
Control AI bots: allow or block each crawler, eyes open
The Access Manager lets you block AI bots selectively — allow or block every AI crawler individually, grouped by operator, with the consequence of each choice spelled out — so you can block AI model training (GPTBot, ClaudeBot, Google-Extended) without disappearing from ChatGPT or Perplexity answers. Presets, a preview of the exact robots.txt lines, and nothing written until you save.
AI readiness score: optimize for AI search (GEO / AEO)
Generative engine optimization starts with what AI systems can actually use. The AI SEO readiness score runs 18 checks — access, discovery, structure, depth, trust and internal linking — and ranks the open issues by impact, each with a plain-language fix and the pages to start with.
Opportunities from your own crawl data
What should you do next? The Opportunities screen answers from observed data: crawlers you block whose assistants already send you visitors, important pages no AI crawler has read, pages crawled often but not answer-ready, and pages that error or respond slowly to crawlers.
Publish check, alerts, and the posts list
The editor warns before you publish a page that is noindex, blocked by robots.txt, canonicalised elsewhere or too thin for AI search. Alerts (email or webhook — Slack, Teams, Google Chat) fire when something changes: a new AI crawler, robots.txt suddenly blocking AI search, impersonation attempts, a drop in your readiness score. The posts list gains a sortable AI column.
Honest data: observed vs. suggested
Everything is labelled with where it comes from. Real requests, real server responses and your own content are marked Observed. AI assistants do not tell websites what people asked them, and this plugin never presents a generated suggestion as a real query.
Private and local by default
The plugin ships with a bundled crawler registry and works completely offline. Visitors are never tracked; crawler addresses are stored truncated. Optional remote updates and the optional RankyFy account are both opt-in — see External Services below.
Works beside your SEO plugin
RankyFy AI SEO complements Yoast SEO, Rank Math, SEOPress and All in One SEO rather than replacing them: classic SEO plugins optimize for search engine rankings, this plugin covers the AI SEO side — crawler access, AI traffic, llms.txt and answer-readiness. The publish check even reads your SEO plugin’s noindex settings to warn you before a page silently drops out of AI search.
Development
The plugin is developed in the open at https://github.com/shivang-dev/rankyfy-wordpress-aibotdetection — issues and pull requests are welcome there.
Everything in this package ships exactly as written: the PHP, the JavaScript (assets/js/admin.js, guard.js, log-worker.js) and the CSS are the hand-written source files themselves. There is no build step, no bundler, no transpiler and no minification, so no separate “source” version exists — what you read is what runs.
External Services
The plugin contacts no external service by default. Each service below is used only after the administrator enables it, and each can be switched off again at any time.
1. RankyFy crawler registry (optional, off by default)
- Service:
https://dashboard.rankyfy.com/— operated by RankyFy (https://rankyfy.com/) - Purpose: fetches an updated registry of AI crawler identities and a consolidated copy of the operators’ published network ranges, so new crawlers are recognised without a plugin update.
- When: only when “Keep crawler data updated from the internet” is enabled in Settings Capture, or when the administrator clicks “Update now” on the registry screen. Checked at most twice a day.
- Data sent: a standard HTTP request whose user-agent contains the plugin version and the site’s address. No visitor data, no content.
- Privacy policy: https://rankyfy.com/privacy-policy/ — Terms: https://rankyfy.com/terms/
2. Crawler operators’ published files (optional, off by default; same switch as above)
- Purpose: verifying that a request claiming to be a known crawler really came from that crawler, by comparing it against the address lists and signing keys the operators themselves publish.
- Data sent: a plain, anonymous HTTP GET to a fixed public file; the user-agent names the plugin. No site content, no visitor data, nothing about your WordPress installation.
- When: at most once a day per file, in the background, and only while the opt-in is enabled.
- The published IP-range files fetched, and each operator’s privacy policy:
- OpenAI —
openai.com(https://openai.com/policies/privacy-policy/) - Anthropic —
claude.com(https://www.anthropic.com/legal/privacy) - Perplexity —
www.perplexity.com(https://www.perplexity.ai/hub/legal/privacy-policy) - Google —
developers.google.com(https://policies.google.com/privacy) - Microsoft Bing —
www.bing.com(https://www.microsoft.com/privacy/privacystatement) - Apple —
search.developer.apple.com(https://www.apple.com/legal/privacy/) - Common Crawl —
index.commoncrawl.org(https://commoncrawl.org/privacy-policy) - DuckDuckGo —
duckduckgo.com(https://duckduckgo.com/privacy)
- OpenAI —
- Web Bot Auth key directories: when a crawler signs its requests (RFC 9421), its public keys are fetched from the
/.well-known/http-message-signatures-directorypath of the host the crawler itself names in its Signature-Agent header — always over HTTPS, never to private addresses, capped per hour. - Cloudflare’s public edge list —
www.cloudflare.com/ips-v4and/ips-v6(https://www.cloudflare.com/privacypolicy/, terms: https://www.cloudflare.com/website-terms/): fetched weekly so that sites behind Cloudflare can trust its visitor-address header without manual setup. The request carries no data about your site.
3. RankyFy account services (optional, requires the separate RankyFy SEO plugin and a connected account)
- Service:
https://dashboard.rankyfy.com/— operated by RankyFy (https://rankyfy.com/) - Purpose and data sent: (a) if “Help identify new AI crawlers” is enabled, the user-agent text of unrecognised bots — nothing else; (b) when the administrator explicitly requests AI analysis of a page, that page’s content, title and address.
- When: never without a connected account, and (b) only on an explicit per-page request or when automatic analysis is switched on.
- Privacy policy: https://rankyfy.com/privacy-policy/ — Terms: https://rankyfy.com/terms/
4. Webhooks (optional)
Alert notifications can be sent to one HTTPS endpoint the administrator configures (for example Slack or Microsoft Teams). Only the alert title and text are sent.
The plugin also makes one daily request to the site’s own address to test how the server answers crawlers; that request never leaves the site’s host.
Data Storage
Stored locally, in the plugin’s own database tables: for each crawler request the time, path, response code, response time, user agent and the network the request came from (the address with its last part removed, for example 203.0.113.0/24). Full addresses are kept only for a few minutes while a crawler’s identity is verified, then discarded. Ordinary visitors are never recorded; a visit arriving from an AI assistant is kept only as a daily count per page, with no information about the visitor. Retention periods are configurable in Settings (raw requests default to 30 days) and everything is removed on uninstall.
The plugin adds suggested text for your site’s privacy policy under Settings Privacy.
Screenshots
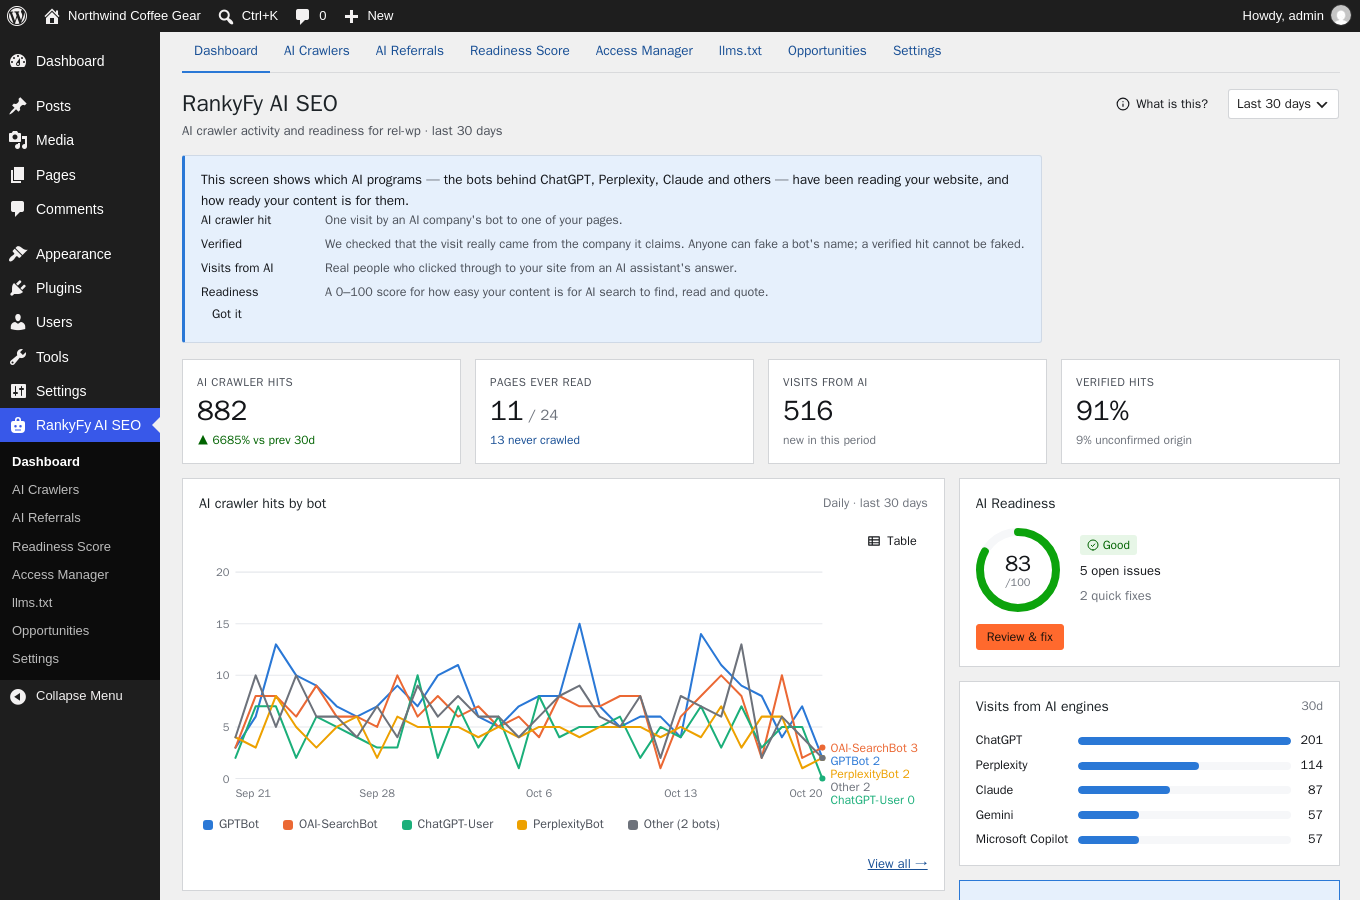
Dashboard — AI crawler hits, pages read, visits from AI assistants and the readiness score.
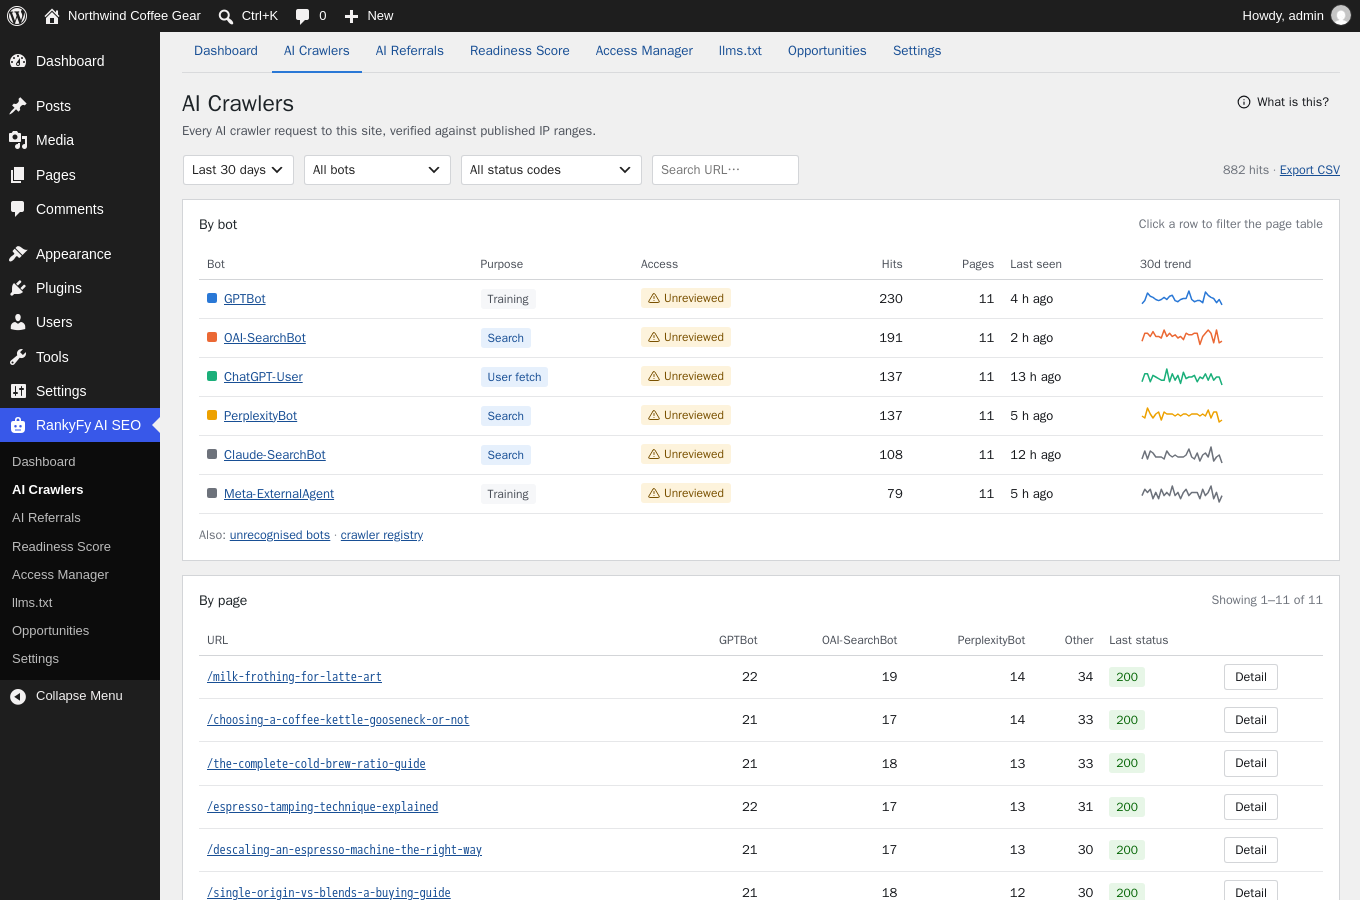
AI Crawlers — every request, verified, with daily trends per bot.
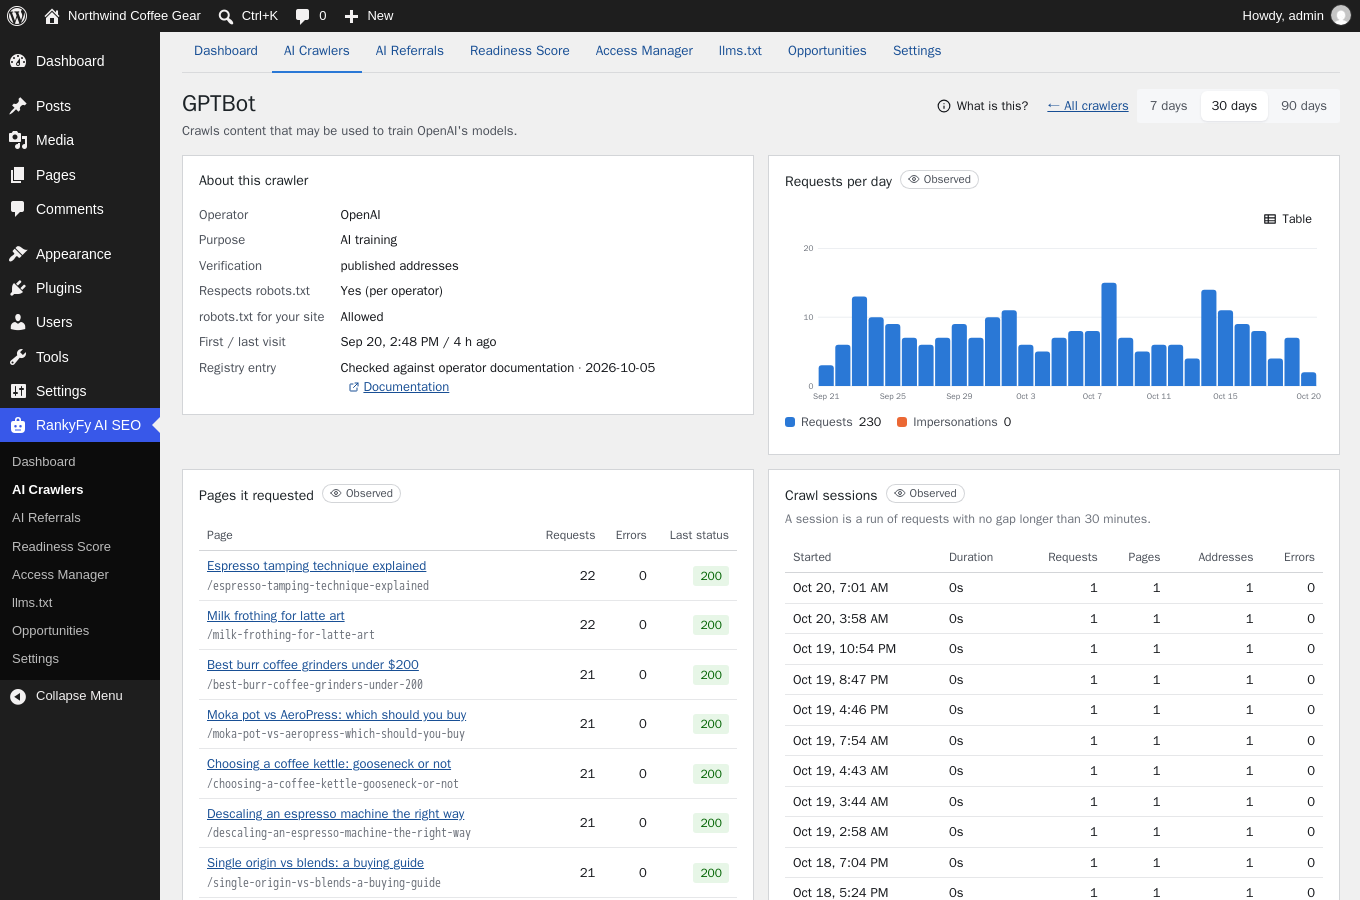
A crawler's detail: GPTBot's requests, verification and the pages it reads.
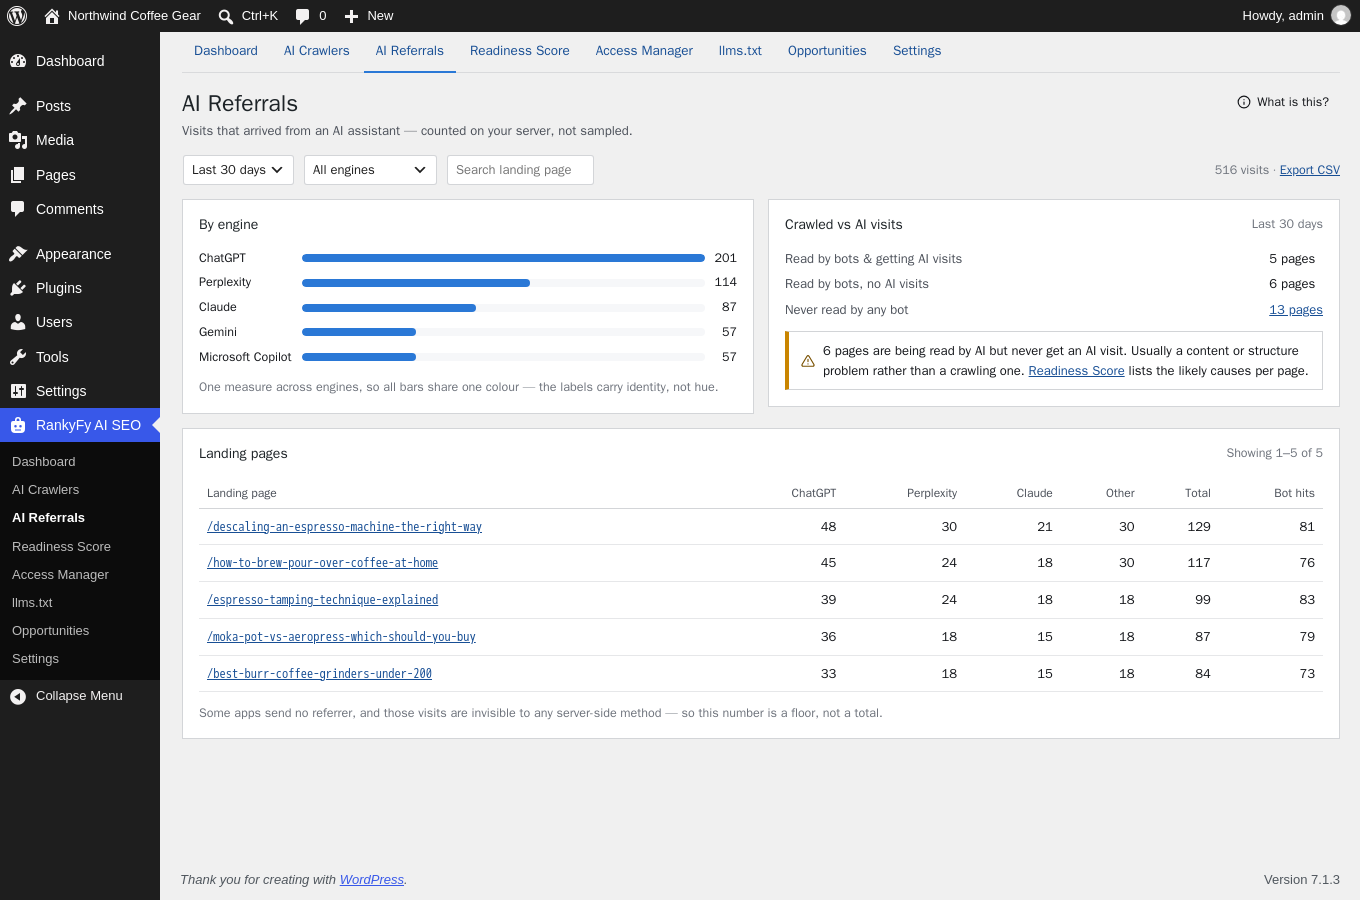
AI Referrals — visits from ChatGPT, Perplexity, Claude and more, beside the crawl data.
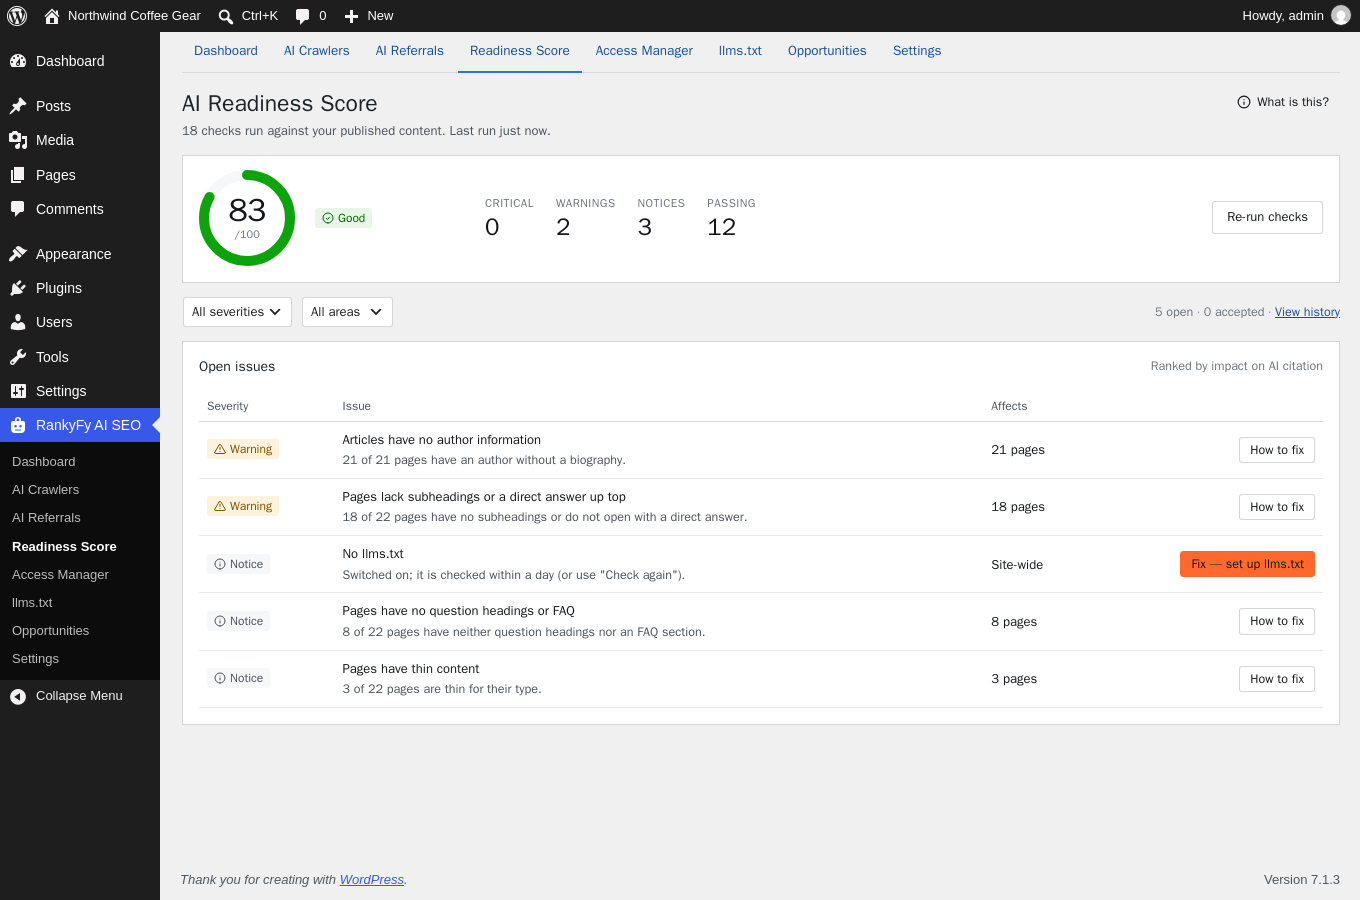
Readiness Score — 18 checks ranked by impact, each with how to fix it.
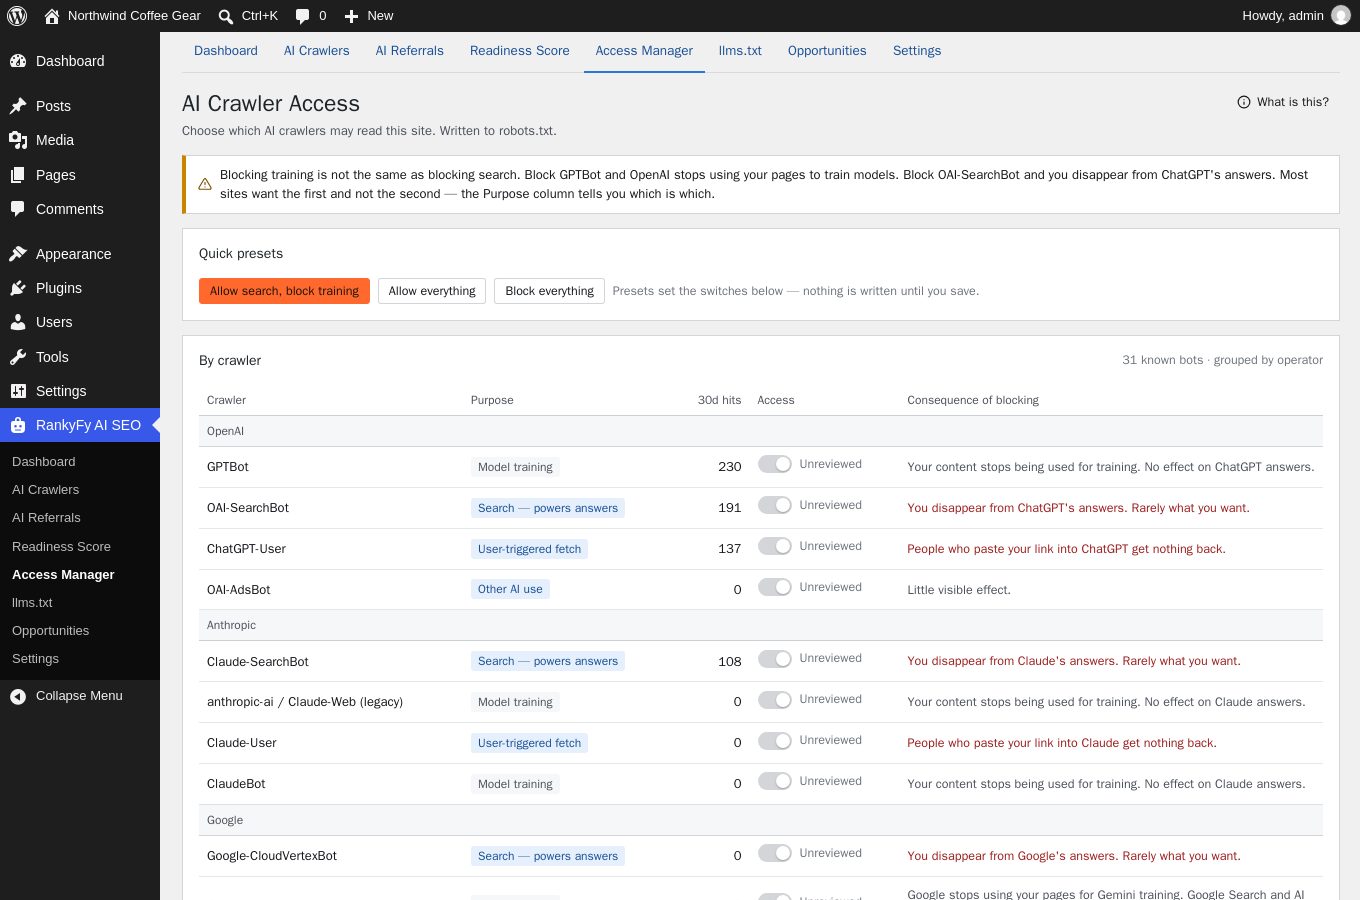
Access Manager — allow or block each AI crawler, with the trade-off spelled out.
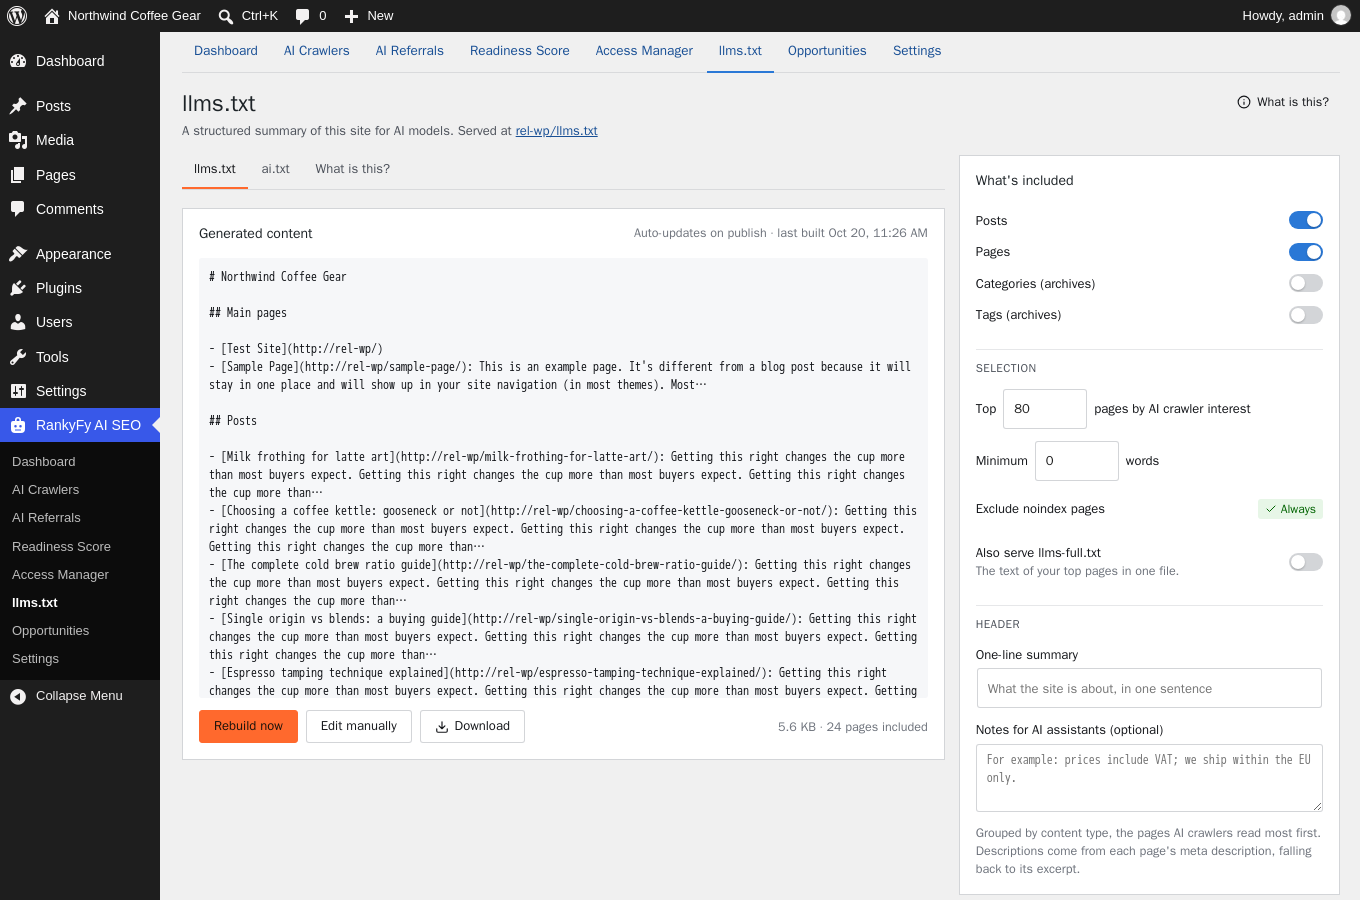
llms.txt — the generated file, what is included and which crawlers fetch it.
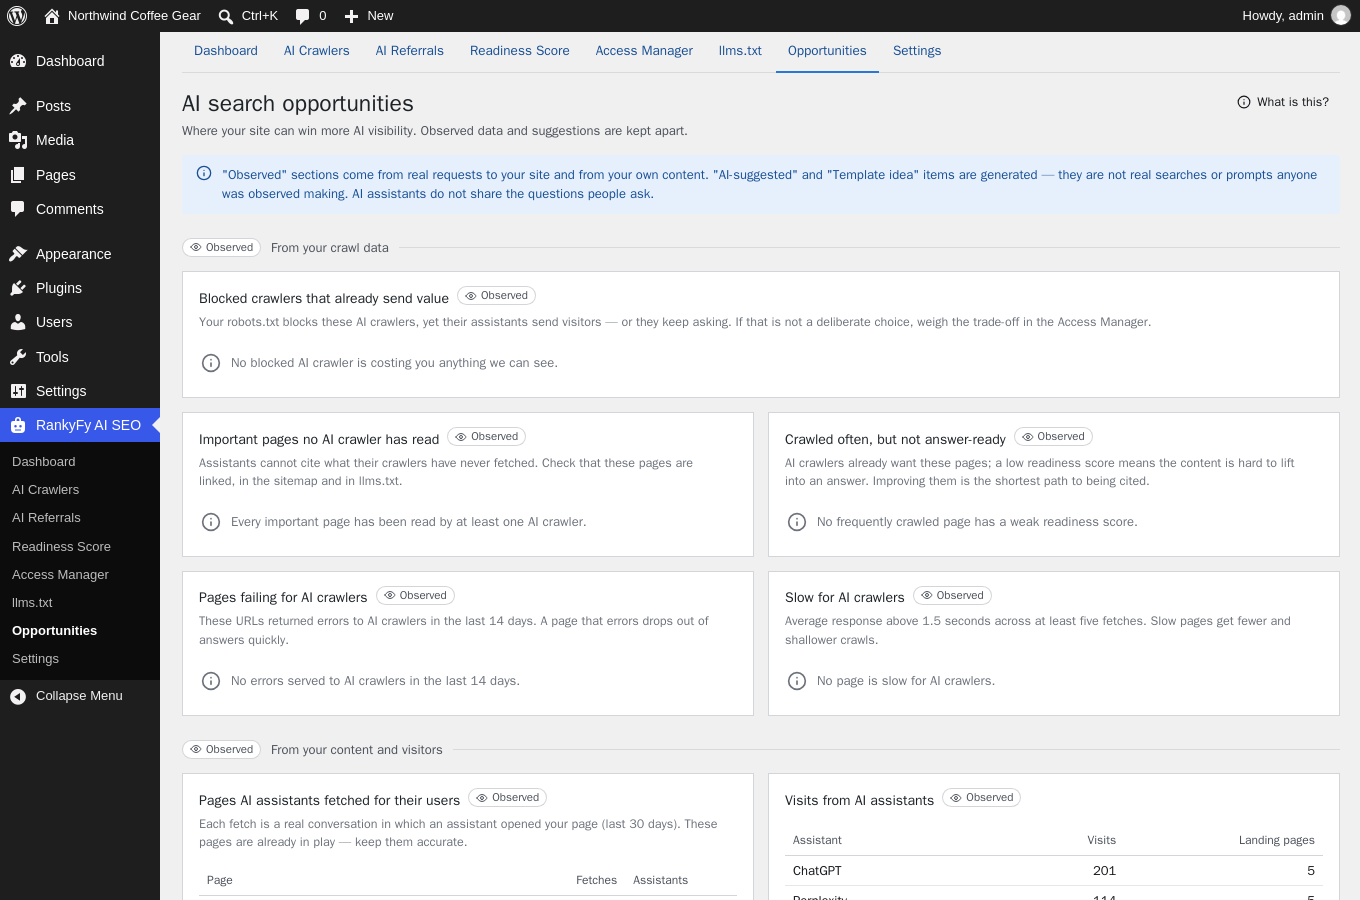
Opportunities — what your own crawl data says to do next.
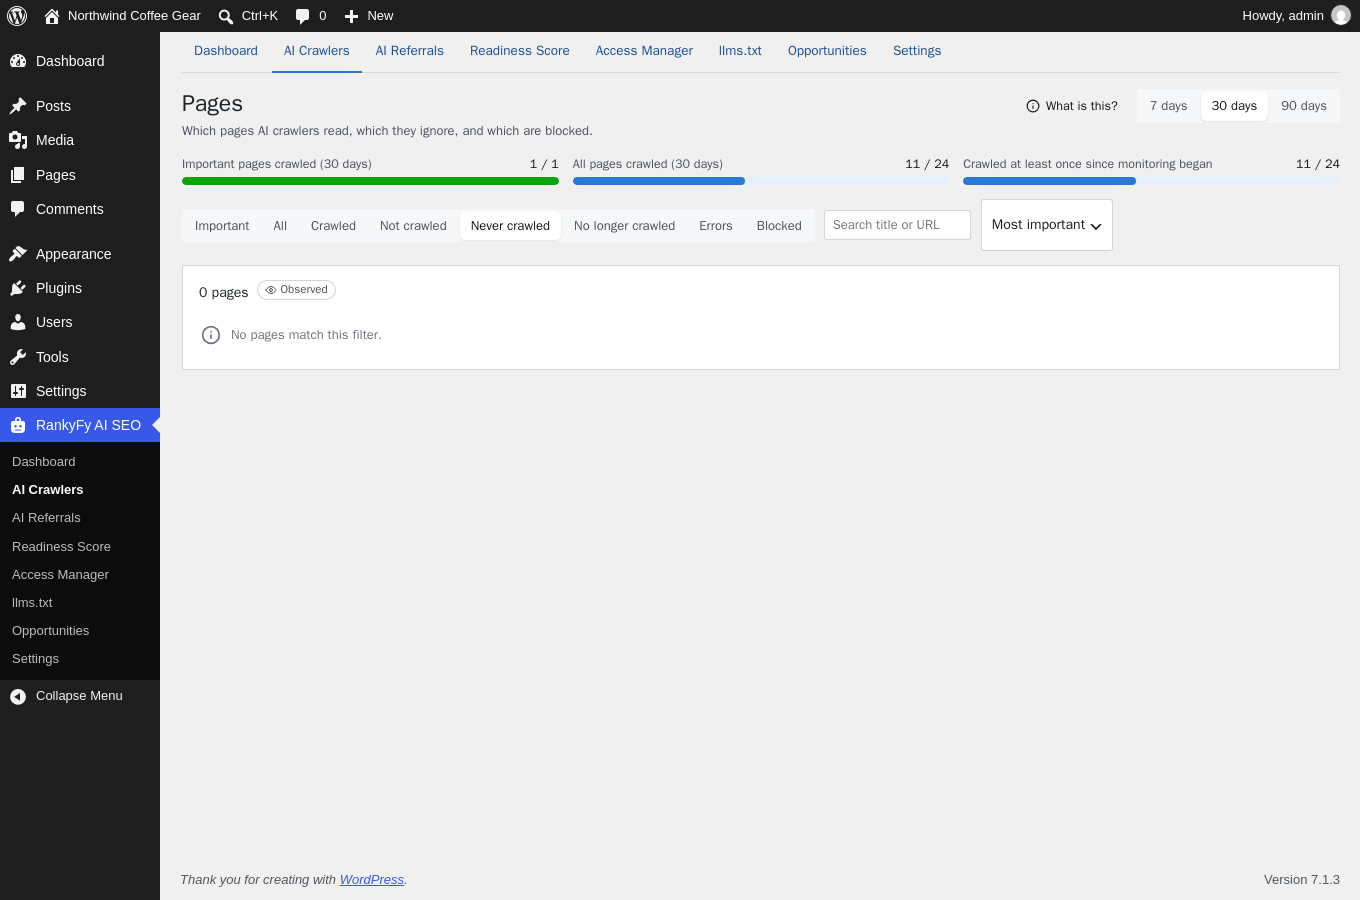
Important pages no AI crawler has read.
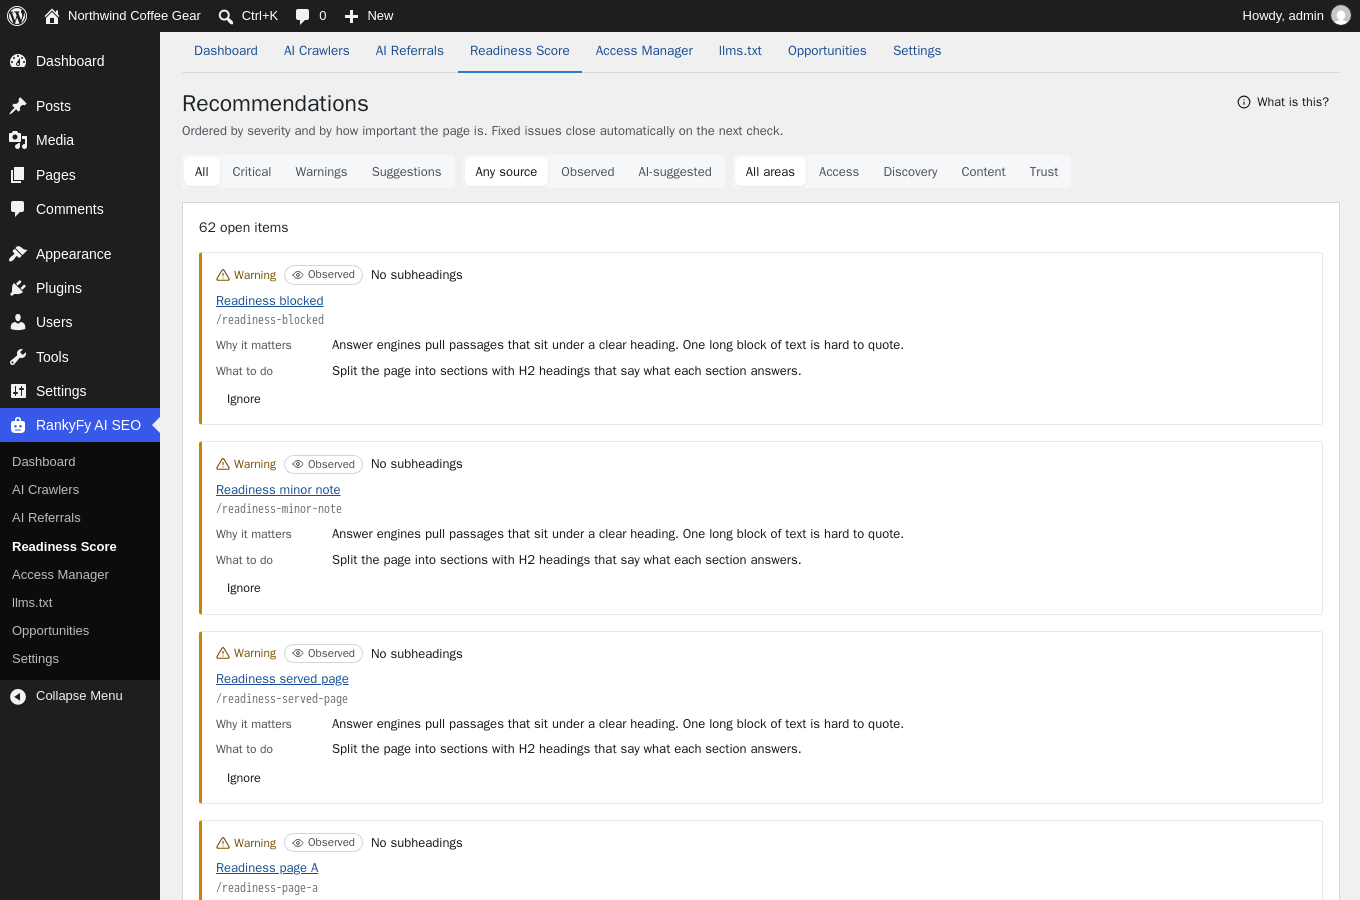
Recommendations, ordered by severity and how important the page is.
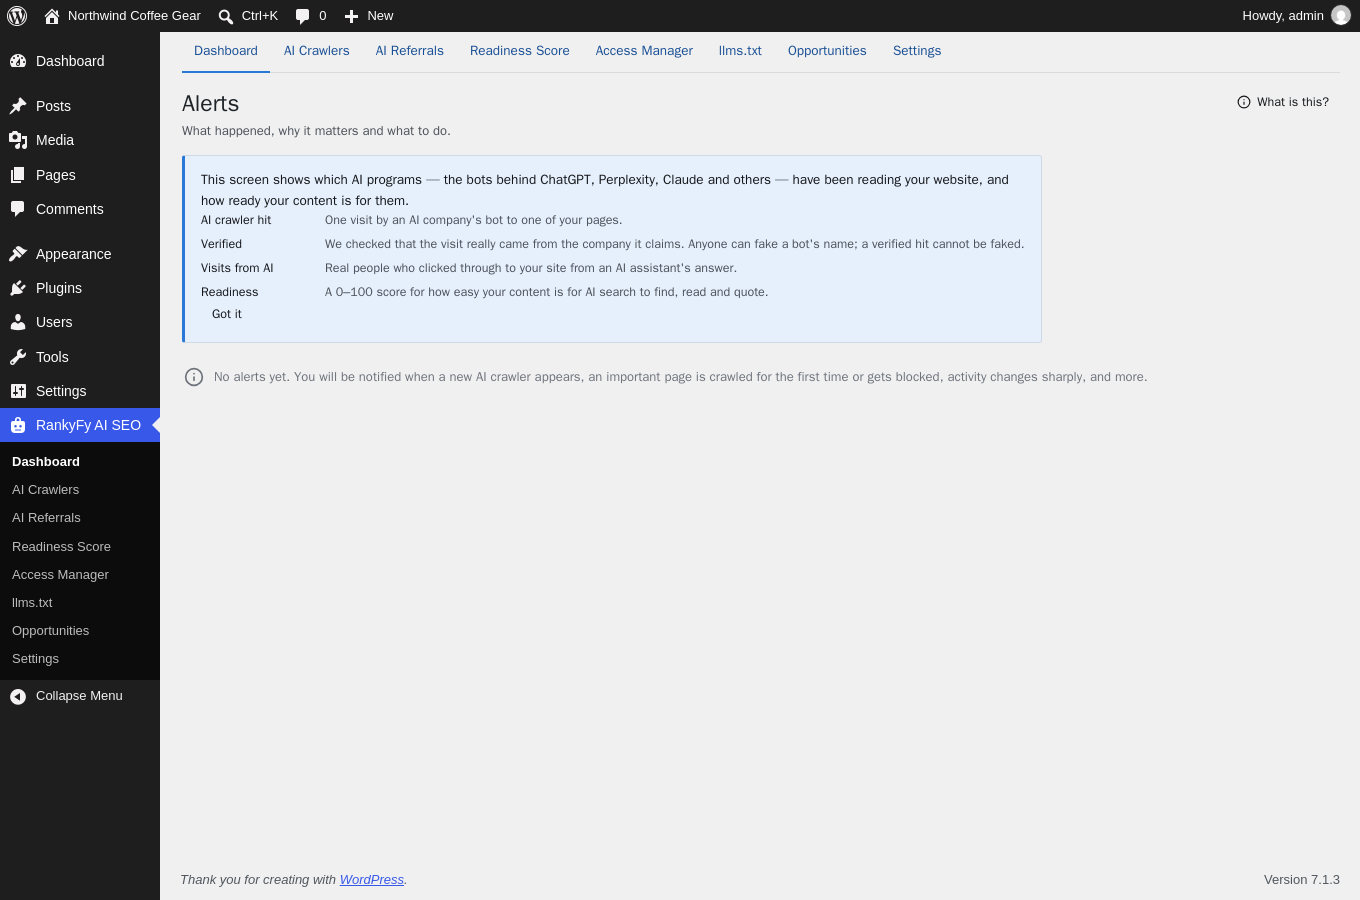
Alerts — new crawlers, blocked crawlers, impersonation, score drops.
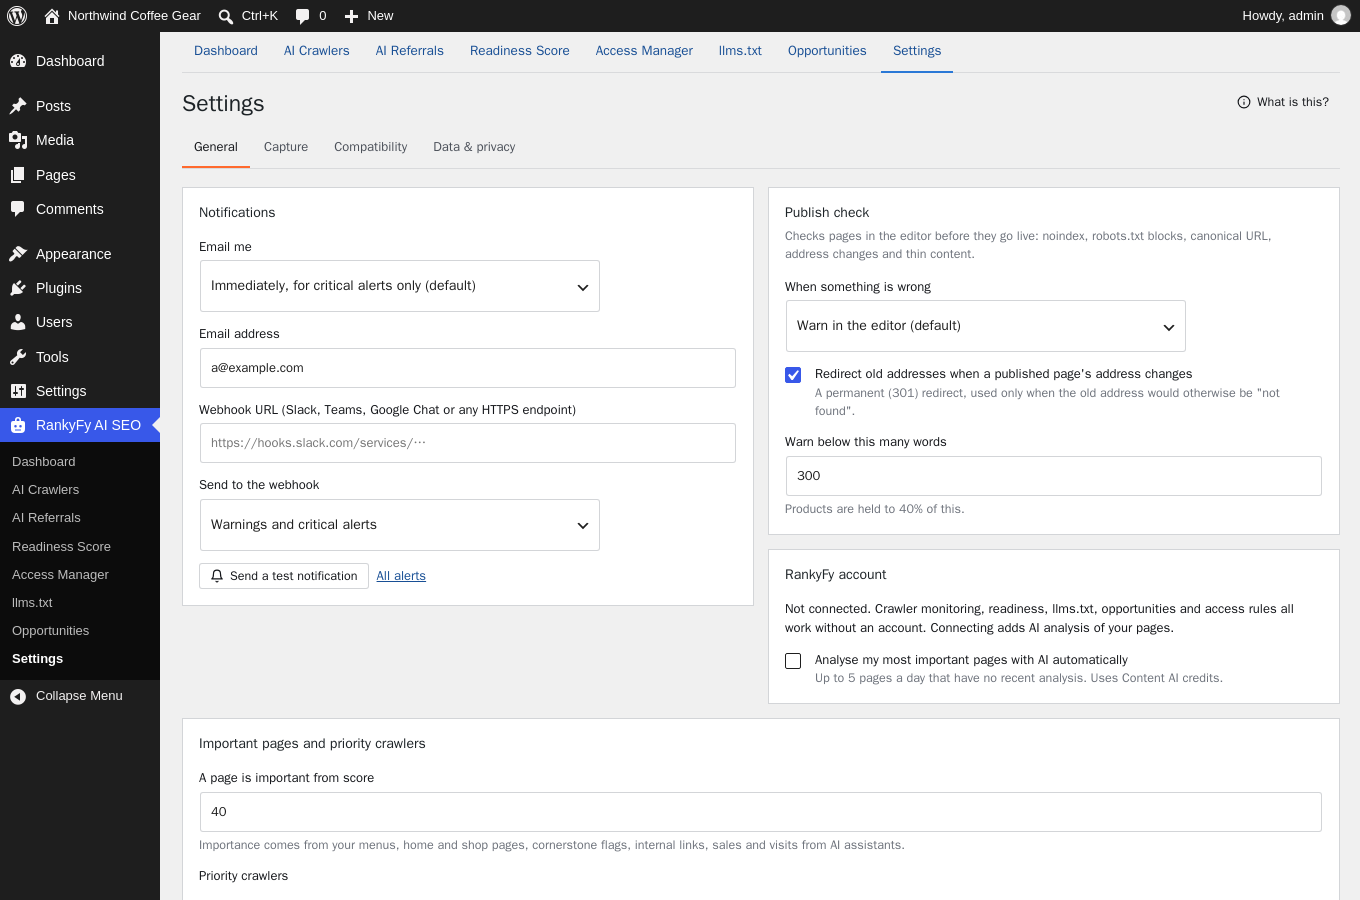
Settings — capture, verification, the remote-updates opt-in, data and privacy.